 VIPSolutions
solve step by step this problem add each step explanation,final conclusion[om [To] [sms To] CLL Lo br] EEENEE EEDD EEENED bo [=r el = ol [=] er] EEDD EEMDD EA EEE I lf) le] B= ===] ==] 5) ff (b) Compute the row percentages. (Round your answers to one decimal place.) | EEE 1) en en) == | =] I EEE B=] =] Fl == [re] = [=] Category A values for x EE — fory. Category B values for x are| fory.
Question:
solve step by step this problem add each step explanation,final conclusion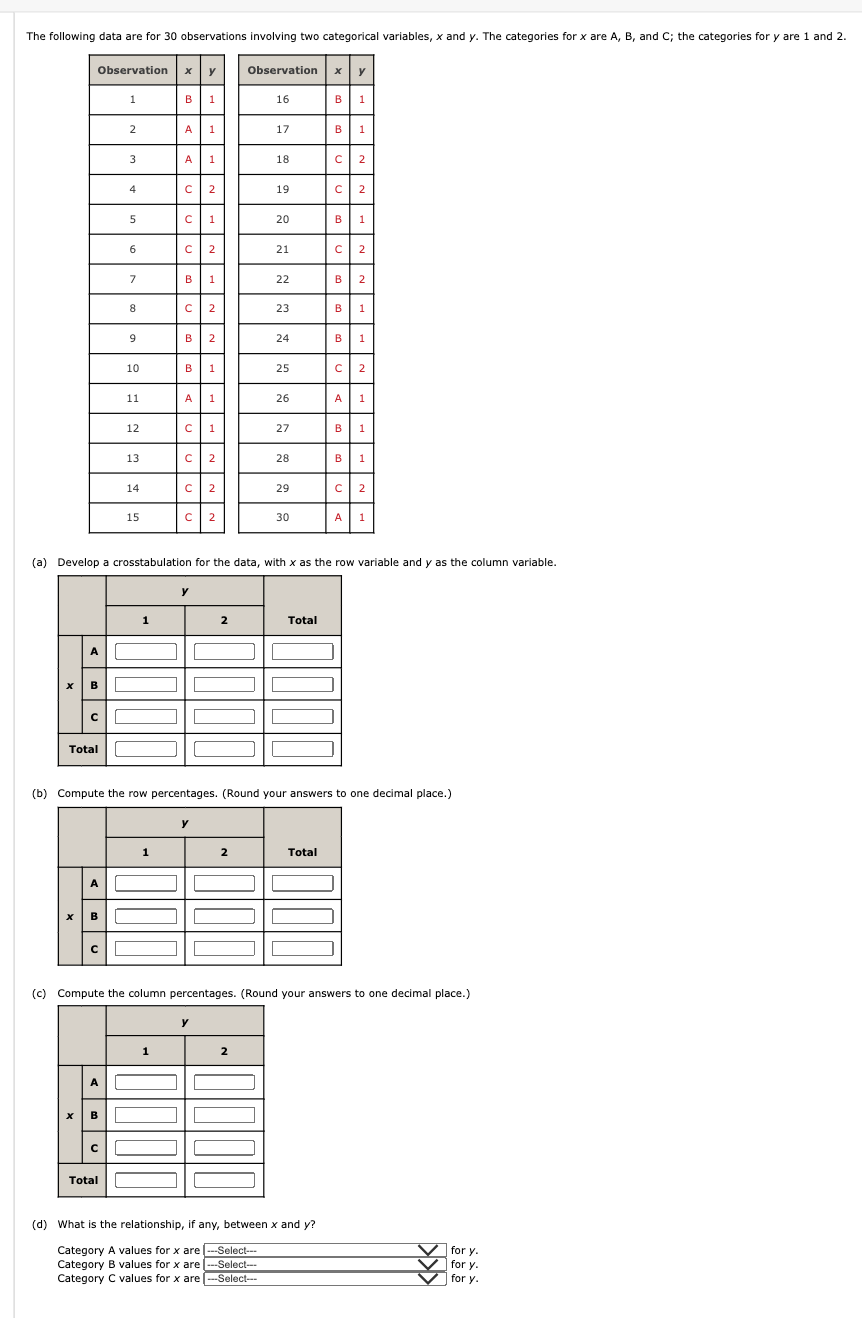 [om [To] [sms To]
CLL Lo
br]
EEENEE
EEDD
EEENED
bo [=r
el =
ol [=]
er]
EEDD
EEMDD
EA
EEE
I lf)
le]
B= ===] ==]
5) ff
(b) Compute the row percentages. (Round your answers to one decimal place.)
|
EEE
1) en en)
==
| =]
I
EEE
B=] =]
Fl
==
[re] = [=]
Category A values for x EE — fory.
Category B values for x are| fory.
This is AI generated Response.
Asked by: Priyanshu Yadav
Created at: 2025-09-29 01:52:48
Asked by: Priyanshu Yadav
Created at: 2025-09-29 01:52:48
Final Answer:
Rendered
Raw Text
Did you like this answer?
Let's solve the step by step:
---
## Step 1: Tally the Counts for Each (x, y) Pair
We'll go through all 30 observations and count the occurrences for each combination of x (A, B, C) and y (1, 2).
### Tally Table
| x | y=1 | y=2 |
|---|-----|-----|
| A | | |
| B | | |
| C | | |
Let's fill this in:
#### For A:
- y=1: Obs 2, 3, 11, 26, 30 → 5 times
- y=2: None
#### For B:
- y=1: Obs 1, 6, 9, 10, 17, 20, 23, 24, 27, 28 → 10 times
- y=2: Obs 7, 22 → 2 times
#### For C:
- y=1: Obs 8 → 1 time
- y=2: Obs 4, 5, 12, 13, 14, 15, 16, 18, 19, 21, 25, 29 → 12 times
Now sum the rows and columns.
---
## Step 2: Crosstabulation Table
### (a) Crosstabulation
| | y=1 | y=2 | Total |
|-----|-----|-----|-------|
| A | 5 | | 5 |
| B | 10 | 2 | 12 |
| C | 1 | 12 | 13 |
|**Total**| 16 | 14 | 30 |
---
## Step 3: Row Percentages
Each cell is: (cell count / row total) × 100
### (b) Row Percentages
| | y=1 | y=2 | Total |
|-----|---------|---------|-------|
| A | 100.% | .% | 5 |
| B | 83.3% | 16.7% | 12 |
| C | 7.7% | 92.3% | 13 |
_Calculations:_
- A-y=1: 5/5 = 1 → 100%
- A-y=2: /5 = %
- B-y=1: 10/12 ≈ .833 → 83.3%
- B-y=2: 2/12 ≈ .167 → 16.7%
- C-y=1: 1/13 ≈ .077 → 7.7%
- C-y=2: 12/13 ≈ .923 → 92.3%
---
## Step 4: Column Percentages
Each cell is: (cell count / column total) × 100
### (c) Column Percentages
| | y=1 | y=2 | Total |
|-----|---------|---------|-------|
| A | 31.3% | .% | 5 |
| B | 62.5% | 14.3% | 12 |
| C | 6.3% | 85.7% | 13 |
|**Total**| 100% | 100% | 30 |
_Calculations:_
- y=1 (total=16): A: 5/16=.313 → 31.3%; B: 10/16=.625 → 62.5%; C: 1/16=.063 → 6.3%
- y=2 (total=14): A: /14=.%; B: 2/14≈.143 → 14.3%; C: 12/14≈.857 → 85.7%
---
## Step 5: Relationship Between x and y
### (d) Relationship
- **Category A values for x are**: highest for y=1
- **Category B values for x are**: highest for y=1
- **Category C values for x are**: highest for y=2
#### Conclusion:
- **A and B** are more likely associated with **y=1**
- **C** is strongly associated with **y=2**
---
## **Final Answers**
### (a) Crosstabulation Table
| | y=1 | y=2 | Total |
|-----|-----|-----|-------|
| A | 5 | | 5 |
| B | 10 | 2 | 12 |
| C | 1 | 12 | 13 |
|**Total**| 16 | 14 | 30 |
---
### (b) Row Percentages
| | y=1 | y=2 | Total |
|-----|---------|---------|-------|
| A | 100.% | .% | 5 |
| B | 83.3% | 16.7% | 12 |
| C | 7.7% | 92.3% | 13 |
---
### (c) Column Percentages
| | y=1 | y=2 | Total |
|-----|---------|---------|-------|
| A | 31.3% | .% | 5 |
| B | 62.5% | 14.3% | 12 |
| C | 6.3% | 85.7% | 13 |
---
### (d) Relationship
- **Category A values for x are**: highest for y=1
- **Category B values for x are**: highest for y=1
- **Category C values for x are**: highest for y=2
---
**Summary:**
There is a clear relationship: x = C is most likely to occur when y = 2, while x = A or B are more likely when y = 1.
Question:
add explanation after each step and give final conclusion
This is AI generated Response.
Asked by: Priyanshu Yadav
Created at: 2025-09-29 01:54:09
Asked by: Priyanshu Yadav
Created at: 2025-09-29 01:54:09
Final Answer:
Rendered
Raw Text
Did you like this answer?
# Step-by-Step Solution
## Step 1: Tally the Counts for Each (x, y) Pair
We begin by identifying the counts of observations for each combination of the categories \( x \) (A, B, C) and \( y \) (1, 2).
### Tally Table
| x | y=1 | y=2 |
|---|-----|-----|
| A | 5 | 0 |
| B | 10 | 2 |
| C | 1 | 12 |
### Explanation
- For each category \( x \):
- **A** had 5 occurrences with \( y=1 \) and none with \( y=2 \).
- **B** had 10 occurrences with \( y=1 \) and 2 with \( y=2 \).
- **C** had 1 occurrence with \( y=1 \) and 12 with \( y=2 \).
## Step 2: Crosstabulation Table
Now, we will organize these counts into a crosstabulation table, including the totals for each row and column.
### (a) Crosstabulation
| | y=1 | y=2 | Total |
|-----|-----|-----|-------|
| A | 5 | 0 | 5 |
| B | 10 | 2 | 12 |
| C | 1 | 12 | 13 |
|**Total**| 16 | 14 | 30 |
### Explanation
- The total number of observations for \( y=1 \) is 16, and for \( y=2 \) is 14, which sums to 30, confirming the table is complete.
## Step 3: Row Percentages
Next, we compute the percentages of each row, which reflect the distribution of \( y \) values within each category \( x \).
### (b) Row Percentages
| | y=1 | y=2 | Total |
|-----|---------|---------|-------|
| A | 100.0% | 0.0% | 5 |
| B | 83.3% | 16.7% | 12 |
| C | 7.7% | 92.3% | 13 |
### Explanation
- **A**: 5 out of 5 → \( 100\% \) for \( y=1 \).
- **B**: \( \frac{10}{12} \times 100 \approx 83.3\% \) for \( y=1 \) and \( \frac{2}{12} \times 100 \approx 16.7\% \) for \( y=2 \).
- **C**: \( \frac{1}{13} \times 100 \approx 7.7\% \) for \( y=1 \) and \( \frac{12}{13} \times 100 \approx 92.3\% \) for \( y=2 \).
## Step 4: Column Percentages
Now, we calculate the percentages for each column, which illustrate the distribution of categories \( x \) within each \( y \) value.
### (c) Column Percentages
| | y=1 | y=2 | Total |
|-----|---------|---------|-------|
| A | 31.3% | 0.0% | 5 |
| B | 62.5% | 14.3% | 12 |
| C | 6.3% | 85.7% | 13 |
|**Total**| 100% | 100% | 30 |
### Explanation
- **y=1**:
- \( A: \frac{5}{16} \times 100 \approx 31.3\% \)
- \( B: \frac{10}{16} \times 100 \approx 62.5\% \)
- \( C: \frac{1}{16} \times 100 \approx 6.3\% \)
- **y=2**:
- \( A: \frac{0}{14} = 0.0\% \)
- \( B: \frac{2}{14} \times 100 \approx 14.3\% \)
- \( C: \frac{12}{14} \times 100 \approx 85.7\% \)
## Step 5: Relationship Between x and y
We now analyze the relationships between the categories \( x \) and \( y \).
### (d) Relationship
- **Category A values for x are**: highest for \( y=1 \).
- **Category B values for x are**: highest for \( y=1 \).
- **Category C values for x are**: highest for \( y=2 \).
### Conclusion
- Categories \( A \) and \( B \) are more likely associated with \( y=1 \).
- Category \( C \) shows a strong association with \( y=2 \).
## Final Summary
- **Crosstabulation** shows how the counts are distributed across different categories.
- **Row Percentages** indicate the proportion of each \( y \) within each \( x \).
- **Column Percentages** reflect the proportion of each \( x \) within each \( y \).
This analysis helps to understand the relationship between categorical variables \( x \) and \( y \), highlighting the associations clearly.
📢 Instructions:
- Ask anything relatd to above question only.
- For new Question goto :